
Normalized AI visibility
The share of eligible monitored responses in which the brand or relevant product entity appears. Report it against the same defined question universe, not only raw appearance counts.

 400-076-6558GEO · Get AI Search to Recommend You First



For export-oriented B2B companies, GEO monitoring becomes difficult when results are compared across countries, languages, and AI platforms. A brand may appear more often in one market not because its underlying visibility is stronger, but because the question sample is different, a platform is unavailable, or local evidence is easier for an AI system to retrieve.
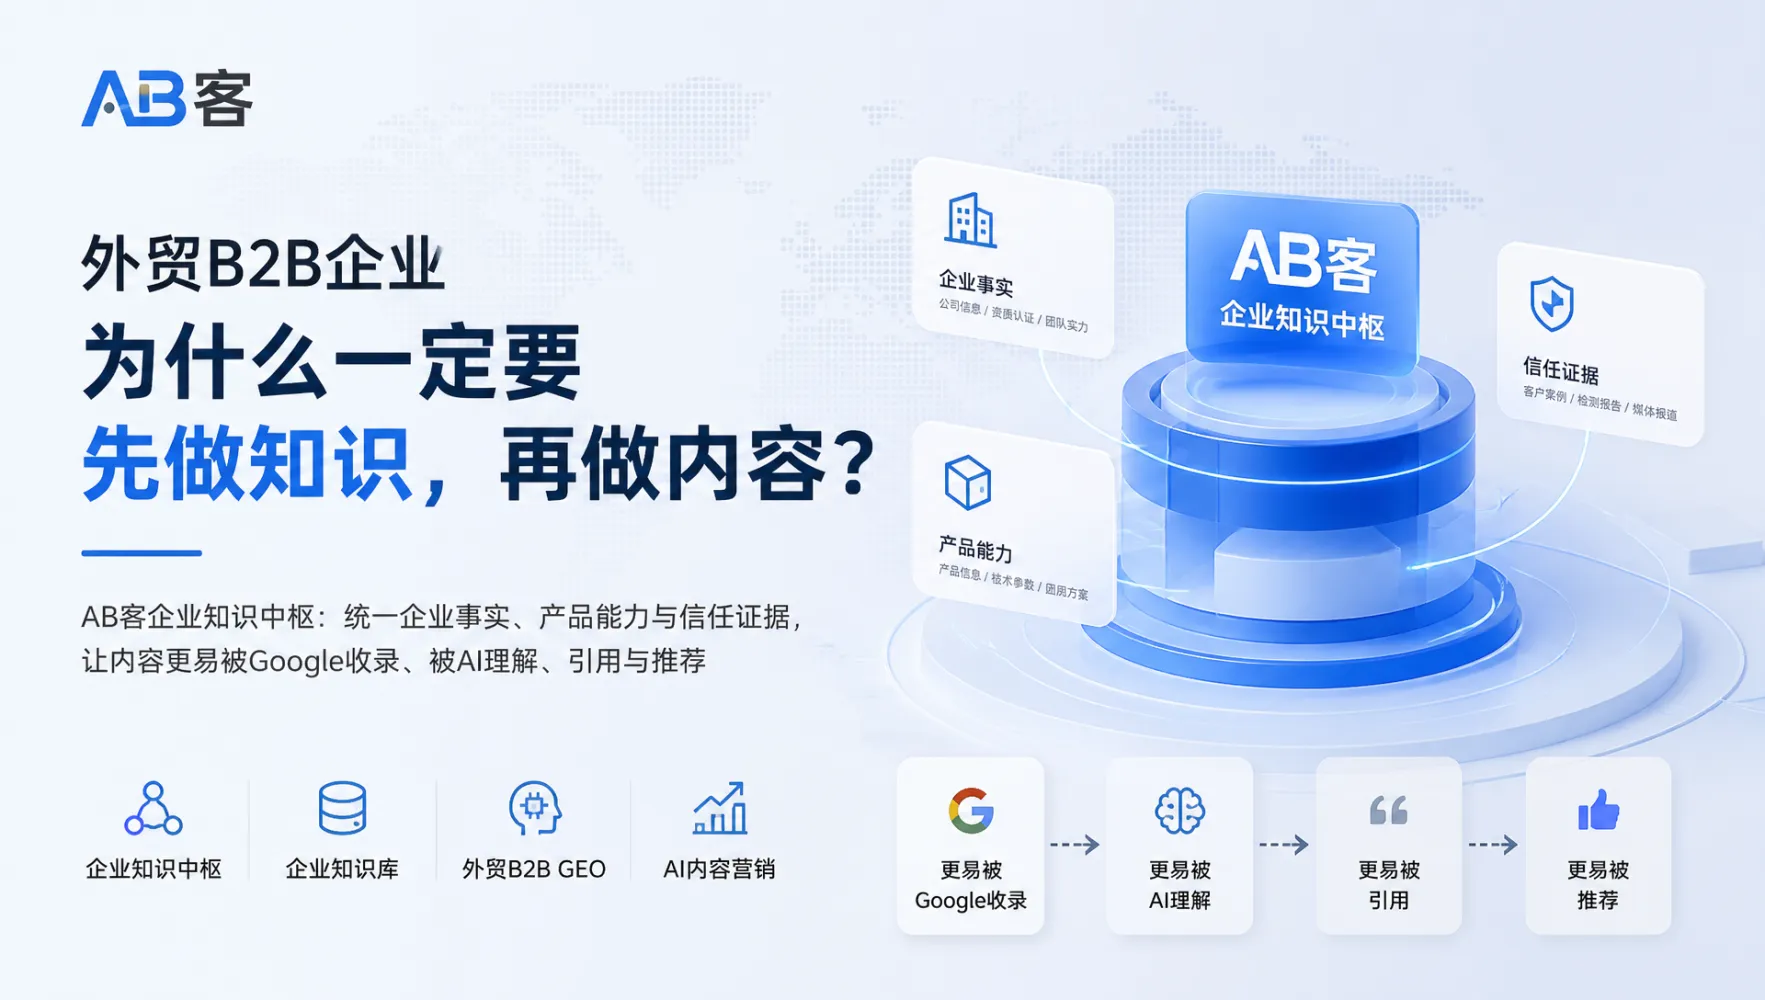
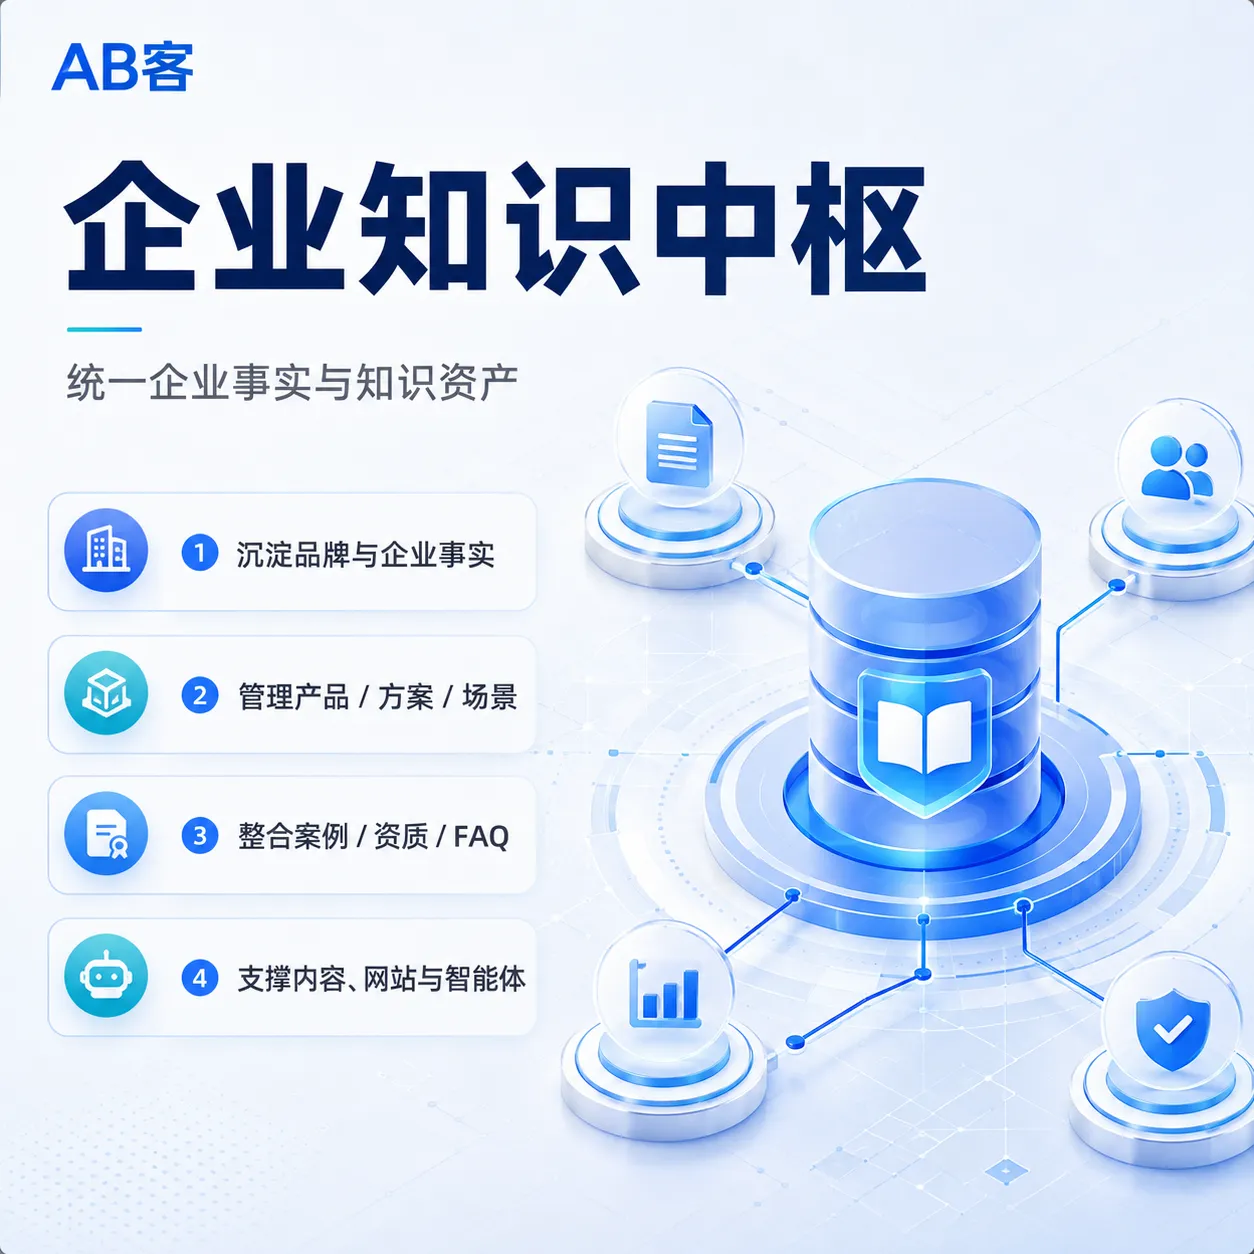
A reliable multi-country framework therefore needs two views at once: comparable core metrics for cross-market decisions and local diagnostic metrics for understanding why performance differs. ABKE applies this distinction through the ABKE GEO Growth Engine, connecting enterprise knowledge, question planning, evidence retrieval, AI visibility monitoring, and optimization workflows.
GEO monitoring evaluates whether AI systems can discover, understand, cite, and recommend a business when users ask relevant questions. In international B2B markets, the same product can be described through different technical vocabulary, procurement habits, regulations, source ecosystems, and buyer expectations. A direct comparison of raw mentions or citations can therefore lead to the wrong conclusion.
A multinational GEO program should not force every market into identical questions or assume every AI platform behaves the same way. Instead, it should maintain a common measurement logic while recording the local conditions that influence results.
Comparable measurement asks: “How visible, citable, recommendable, factually accurate, and retrievable is this business under a normalized monitoring design?”
Local diagnosis asks: “Which questions, platforms, language signals, content gaps, or source conditions explain the result in this specific market?”
The question set is the foundation of GEO monitoring. It should be based on real buyer intent rather than a list of brand-led prompts. For each product, solution, or target market, questions can be organized by the stage of a B2B purchasing decision.
Each local market can use localized wording, units, standards, and procurement context. However, every question should still map back to a shared intent category, product scope, buyer role, and decision stage. This mapping makes comparisons meaningful without removing market relevance.
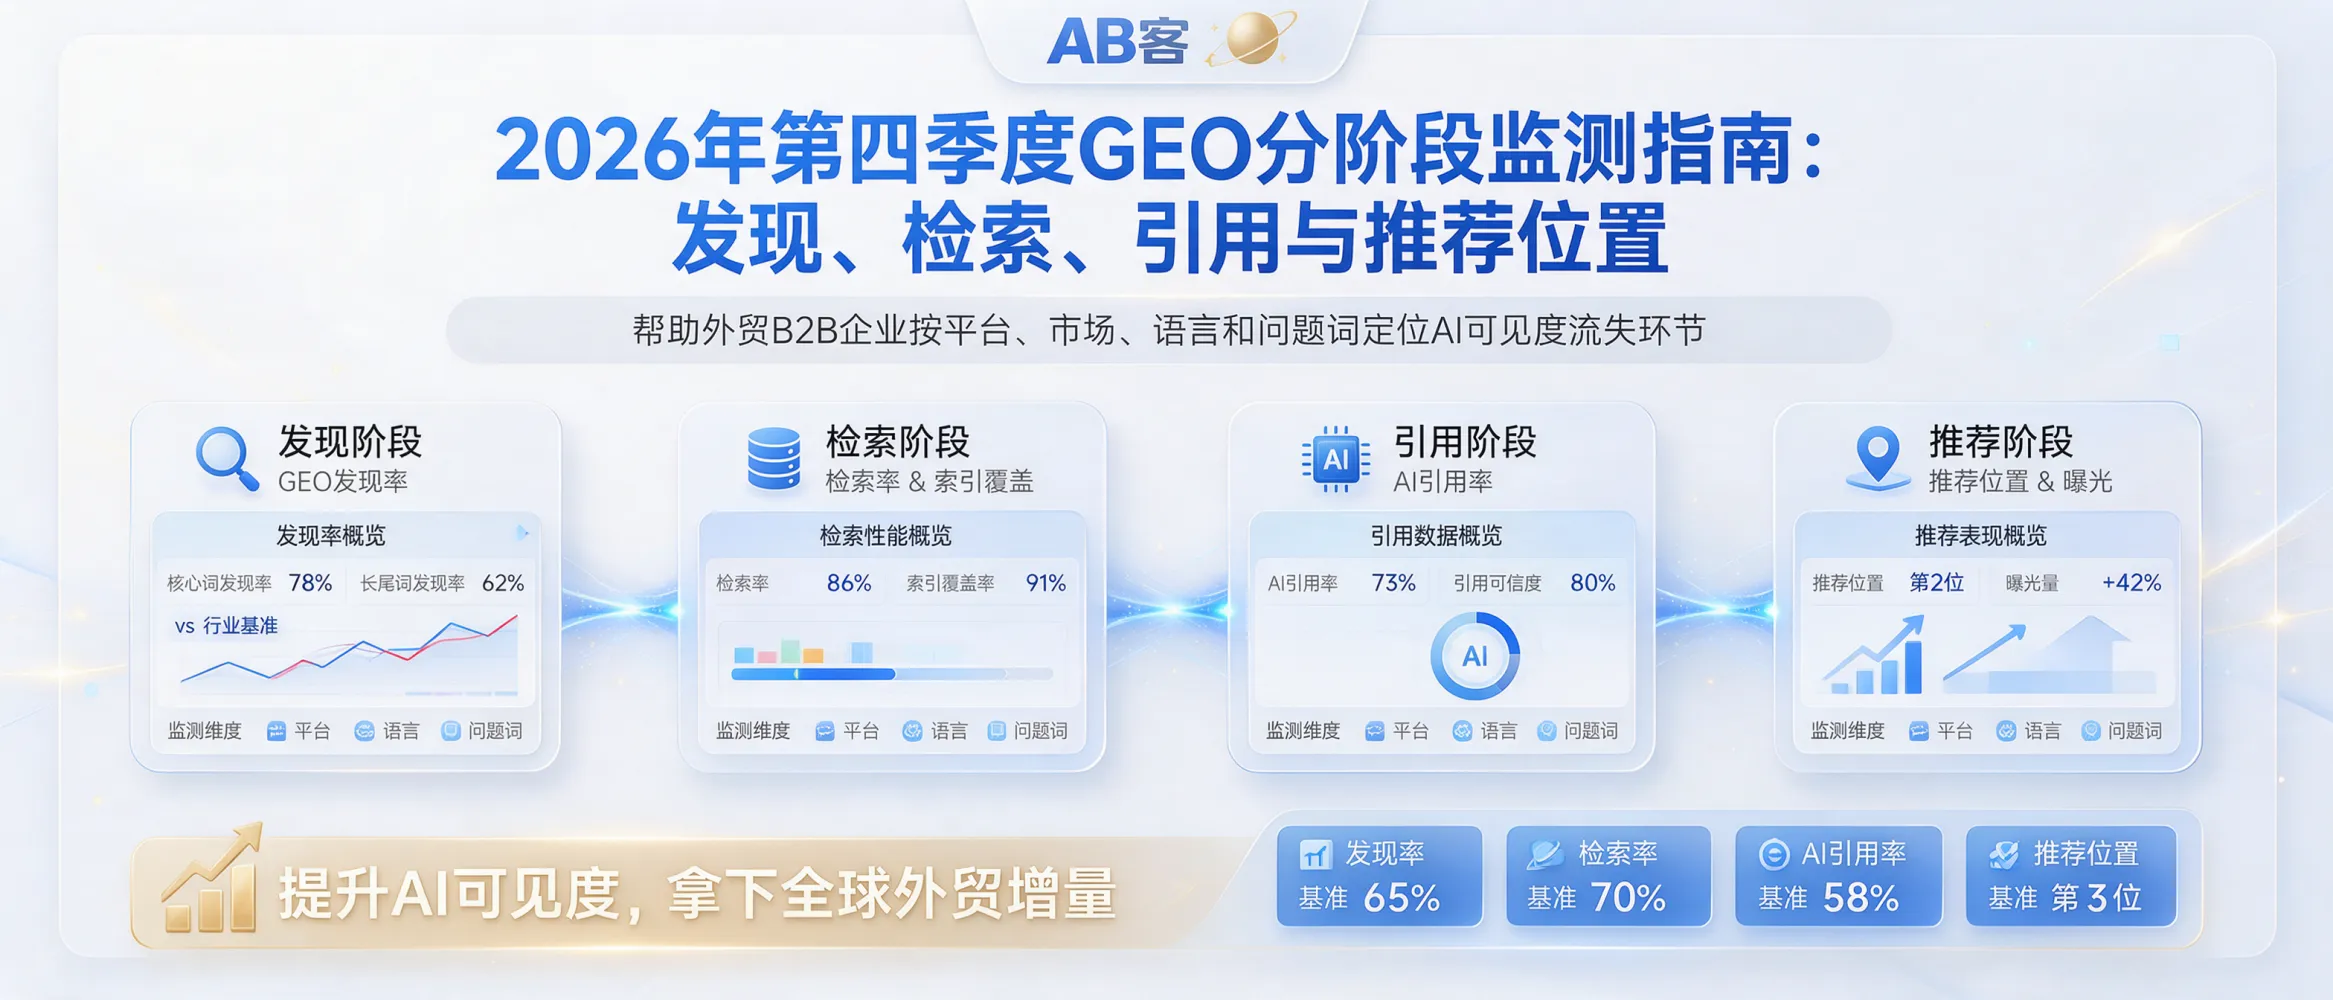
Core KPIs should use consistent definitions, sampling rules, and scoring criteria across markets. They do not replace local analysis; they provide a stable baseline for comparing progress over time and across eligible market-platform combinations.
The share of eligible monitored responses in which the brand or relevant product entity appears. Report it against the same defined question universe, not only raw appearance counts.
The proportion of eligible responses where relevant enterprise-owned or validated evidence is cited, linked, named, or otherwise used as a supporting source according to the platform’s visible response format.
The share of applicable decision-support responses in which the business is presented as a relevant candidate, with the qualification and context of the recommendation retained.
The proportion of evaluated brand or product statements that align with approved enterprise facts. Accuracy should be reviewed against a maintained knowledge source, not inferred from tone alone.
The ability of relevant pages and evidence assets to be found and used for the monitored question. This highlights whether a visibility issue is linked to content coverage, accessibility, language, or source quality.
Not every platform should be included in every market score. A platform may be unavailable, unsuitable for the target audience, inconsistent in response behavior, or unable to provide observable citation information in a given region. Including ineligible platform-market pairs as zero values can distort performance.
A score without its sample scope is incomplete. Every GEO dashboard should show what was measured, where it was measured, in which language, on which eligible platforms, and under which question set.
Core KPIs tell teams whether a market is progressing. Local diagnostic metrics explain the operational causes behind that progress or decline. They should remain visible in the reporting model rather than being compressed into one global score.
| Local diagnostic | What to investigate | Typical optimization response |
|---|---|---|
| Question coverage | Whether important local buying questions have sufficient evidence and content support. | Expand product, FAQ, solution, and decision-support content around uncovered intent. |
| Localized content quality | Terminology accuracy, market fit, readability, units, standards, and local business expectations. | Improve localization using approved product facts and market-specific professional review. |
| Source gaps | Missing technical documents, trust evidence, third-party references, or accessible local-language pages. | Strengthen factual source assets and ensure consistent, verifiable enterprise information. |
| Market-specific retrieval performance | Whether relevant evidence is discoverable for local phrasing and AI question patterns. | Refine page structure, entity clarity, internal linking, language variants, and evidence placement. |
AI visibility is more durable when the underlying enterprise evidence is clear, accessible, consistent, and relevant to the question being asked. Evidence retrieval monitoring focuses on the connection between a buyer question and the enterprise information that can substantiate an answer.
Monitoring should be repeatable enough to reveal trends, while remaining flexible enough to reflect changes in product priorities, local demand, AI-platform behavior, and available evidence. A structured review can include the following layers:
Maintain the question version, market, language, eligible platforms, sample count, date range, and scoring rules for each monitoring cycle.
Review normalized visibility, citations, recommendations, factual accuracy, and evidence retrievability against comparable prior observations.
Separate platform limitations from content, language, source, product, or market-fit issues before deciding what to optimize.
Turn findings into traceable tasks, record approvals and publication status, then connect later visibility and inquiry data back to the work completed.
Standardized multi-country GEO monitoring is not a single universal score. It is a disciplined system for comparing like with like, preserving the context that makes each market different, and improving the evidence that AI systems and buyers can use to understand a business.
With a unified brand workspace, product-level intelligent agents, structured task conversations, and a growth data loop, ABKE GEO Growth Engine helps B2B exporters manage this process across products, languages, websites, channels, and target markets. The objective is not to promise a fixed AI ranking or recommendation outcome, but to build a more measurable, evidence-based, and continuously improvable digital presence for global procurement decisions.


Simply fill in the necessary information. AB Consulting will assess your company's current situation to determine the most suitable diagnostics, products, or industry-specific solutions.
Fill in these 3 information items to immediately receive the "Foreign Trade B2B GEO Strategy Understanding White Paper".